31 May 2026
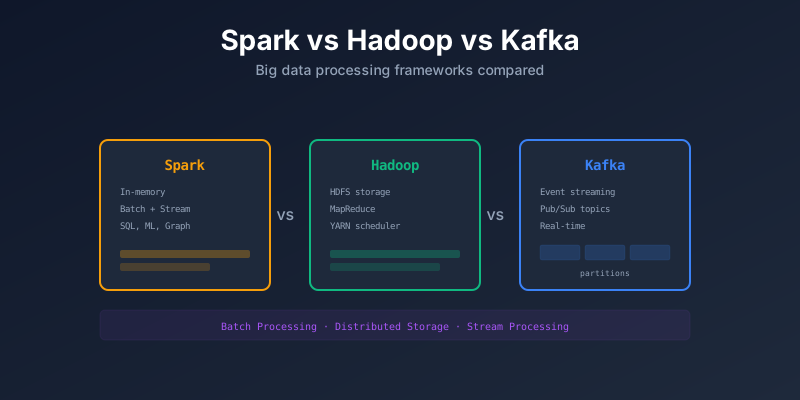
Spark vs Hadoop vs Kafka
A practical comparison of Apache Spark, Hadoop, and Kafka — what each one does and when to use it.
Spark, Hadoop, and Kafka are three pillars of modern data infrastructure. They solve different problems and often work together.
Quick Comparison
| Spark | Hadoop (MapReduce) | Kafka | |
|---|---|---|---|
| What | Distributed compute engine | Distributed storage + compute | Distributed event streaming |
| Purpose | Process data (batch + stream) | Store and process big data | Move data between systems |
| Speed | Fast (in-memory) | Slow (disk-based) | Real-time |
| Data | Processes data | Stores + processes data | Transports data |
| Language | Python, Scala, Java, SQL | Java | Any (producer/consumer) |
Hadoop
The original big data framework (2006). Two main components:
HDFS — Hadoop Distributed File System
Stores files across multiple machines.
File (300MB)
├── Block 1 (128MB) → Node 1, Node 3 (replica)
├── Block 2 (128MB) → Node 2, Node 4 (replica)
└── Block 3 (44MB) → Node 3, Node 1 (replica)- Files split into blocks (default 128MB)
- Each block replicated (default 3 copies)
- NameNode tracks where blocks are stored
MapReduce
The compute engine of Hadoop. Slow because it reads/writes to disk between steps.
Input → Map (disk) → Shuffle (disk) → Reduce (disk) → OutputHadoop Ecosystem
| Tool | Purpose |
|---|---|
| HDFS | Distributed file storage |
| YARN | Resource management |
| Hive | SQL queries on Hadoop |
| HBase | NoSQL database on HDFS |
| Pig | Data flow scripting |
Status: HDFS is still used, but MapReduce has been largely replaced by Spark.
Apache Spark
A fast, general-purpose distributed compute engine. 10-100x faster than MapReduce because it processes data in memory.
Input → Transform (memory) → Transform (memory) → OutputSpark Components
┌─────────────────────────────────┐
│         Spark SQL               │ ← SQL queries
├───────────┬───────────┬─────────┤
│ Spark     │ MLlib     │ GraphX  │
│ Streaming │ (ML)      │ (Graph) │
├───────────┴───────────┴─────────┤
│        Spark Core (RDDs)        │
├─────────────────────────────────┤
│  YARN / Kubernetes / Standalone │
└─────────────────────────────────┘
PySpark Example
from pyspark.sql import SparkSession

spark = SparkSession.builder.appName("example").getOrCreate()

# Read data
df = spark.read.parquet("s3://bucket/sales/")

# Transform
result = (df
    .filter(df.year == 2025)
    .groupBy("region")
    .agg({"revenue": "sum", "orders": "count"})
    .orderBy("sum(revenue)", ascending=False)
)

# Write
result.write.parquet("s3://bucket/results/")
When to Use Spark
- Batch processing of large datasets
- ETL/ELT pipelines
- Machine learning at scale (MLlib)
- Interactive SQL queries (Spark SQL)
- Stream processing (Structured Streaming)
Apache Kafka
A distributed event streaming platform. Think of it as a permanent, ordered log of events.
Producers ──→ Kafka Topics ──→ Consumers
                  │
             ┌────┴────┐
             │Partition0│ [msg1, msg2, msg3, ...]
             │Partition1│ [msg1, msg2, ...]
             │Partition2│ [msg1, msg2, msg3, msg4, ...]
             └─────────┘
Key Concepts
| Concept | What It Is |
|---|---|
| Topic | A category/feed of messages |
| Partition | A topic split for parallelism |
| Producer | Sends messages to a topic |
| Consumer | Reads messages from a topic |
| Consumer Group | Multiple consumers sharing work |
| Offset | Position of a consumer in a partition |
| Broker | A Kafka server |
Kafka Use Cases
| Use Case | How |
|---|---|
| Event sourcing | Store all state changes as events |
| Log aggregation | Collect logs from all services |
| Stream processing | Process events in real-time |
| Data integration | Connect databases, apps, data lakes |
| Microservice communication | Async messaging between services |
Kafka Connect
Move data between Kafka and other systems without code:
Database ──→ Source Connector ──→ Kafka ──→ Sink Connector ──→ S3
PostgreSQL                        Topic                        Data Lake
How They Work Together
Apps/DBs ──→ Kafka ──→ Spark Streaming ──→ Data Lakehouse
                │                               │
                └──→ Spark Batch ──────────→ Data Warehouse
                         │
(reads from HDFS/S3)| Layer | Tool | Role |
|---|---|---|
| Transport | Kafka | Move events in real-time |
| Storage | HDFS / S3 | Store raw data at scale |
| Processing | Spark | Transform and analyze |
| Serving | Database / Warehouse | Serve to users |
Summary
| Tool | Use When |
|---|---|
| Hadoop (HDFS) | Need cheap distributed storage |
| Spark | Need to process/transform large data |
| Kafka | Need real-time data transport between systems |